
Chandra 2.7 is live in the Datalab API, and balanced and accurate modes run on it (fast mode runs Surya 2.6). You don’t need to change anything to use it, and the speed and price are the same.
What’s new:
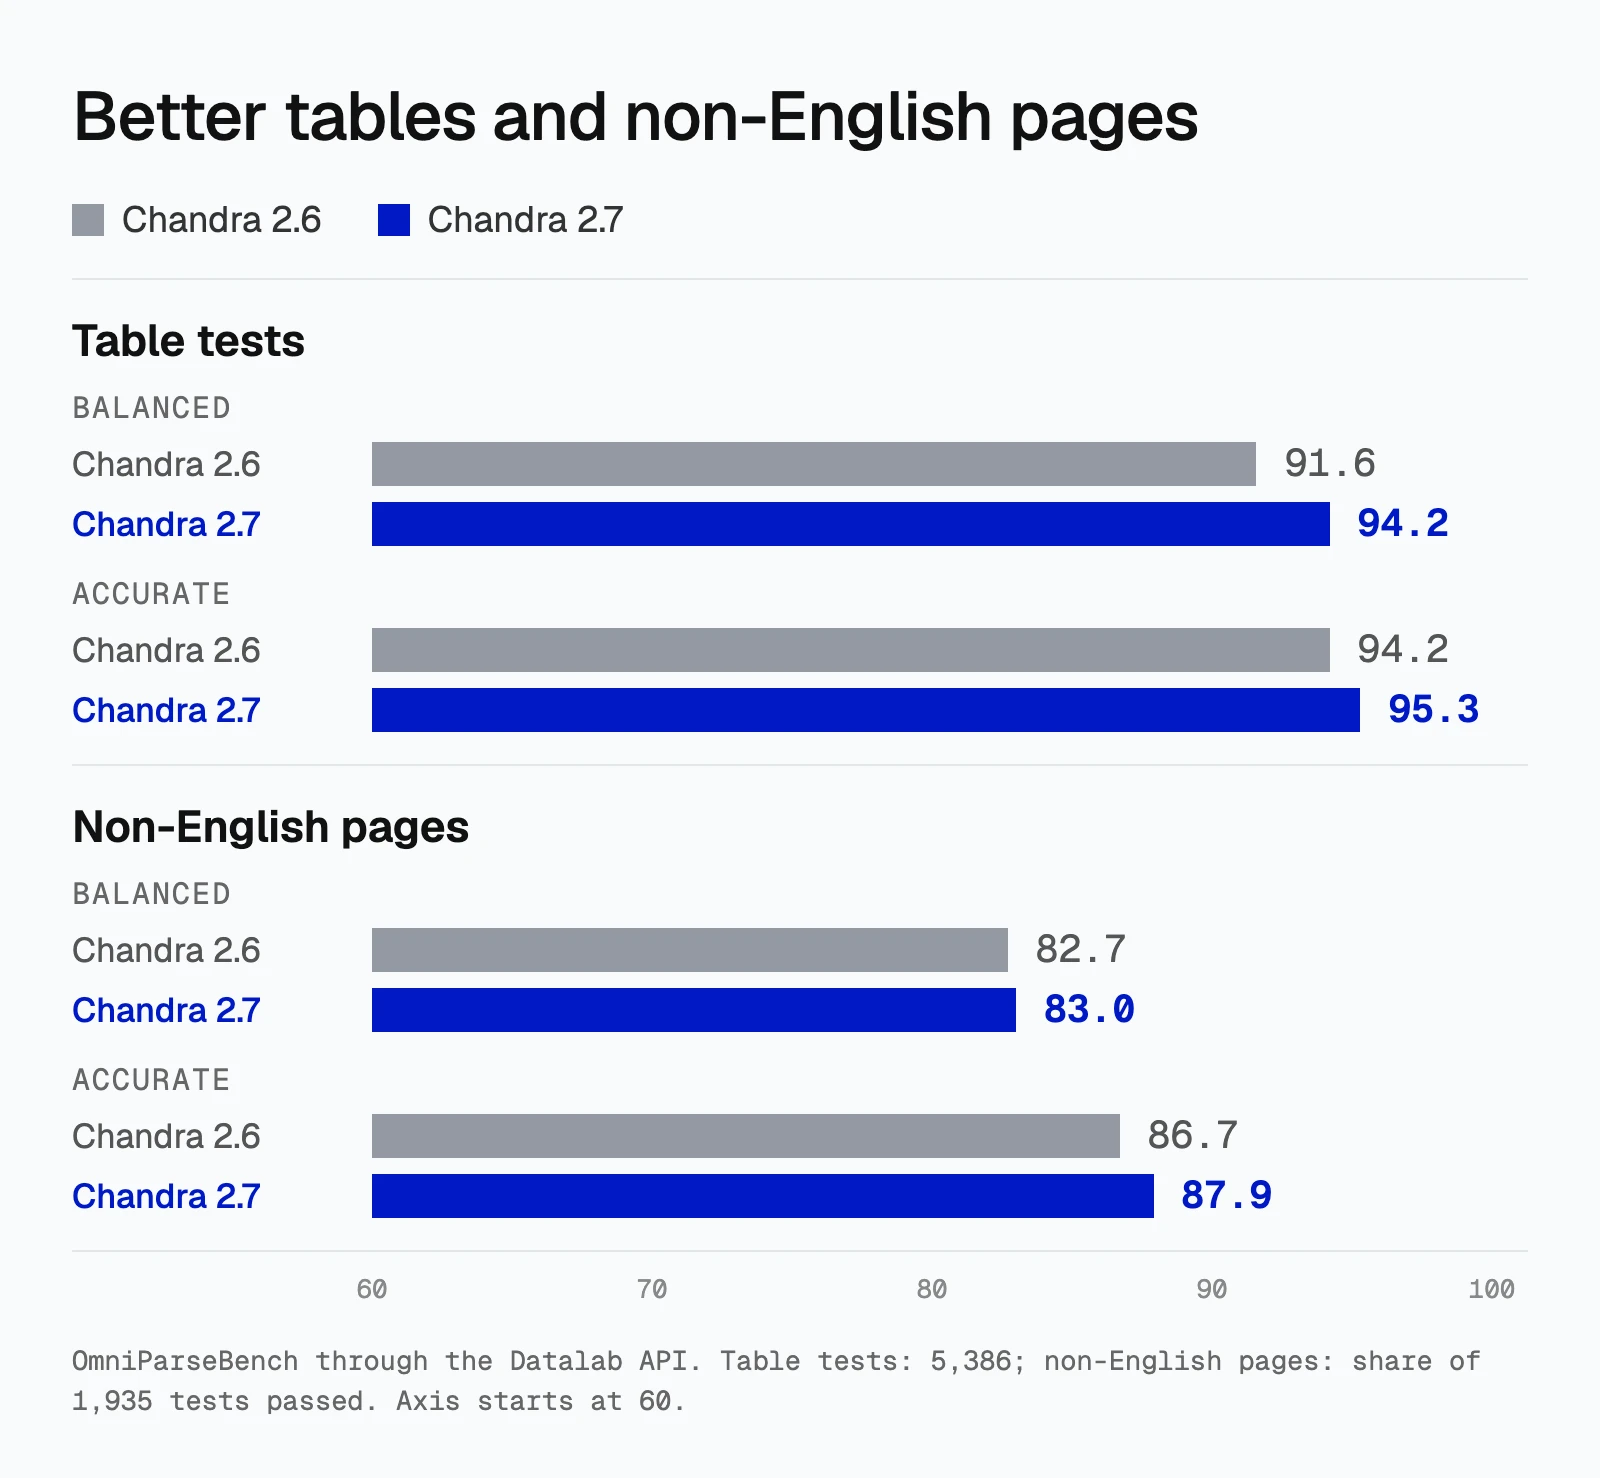
- Better tables. On the OmniParseBench table tests, balanced mode scores 94.2, up from 91.6, and accurate mode 95.3, up from 94.2.
- Better on non-English pages. In accurate mode, 87.9% of their tests pass, up from 86.7%.
- Better on rotated pages. In balanced mode, 87.3% of their tests pass, up from 81.4%.
Better tables
Chandra 2.7 scores higher overall, and most of the gain is in tables. On OmniParseBench, our open parsing benchmark with 16,288 pass/fail tests on 2,937 pages:
| Parser | Overall | Text | Tables | Layout |
|---|---|---|---|---|
| Gemini 4 Argon† | 95.8 | 93.9 | 97.0 | 96.4 |
| Gemini 4 Carbon† | 95.6 | 94.1 | 97.0 | 95.6 |
| Datalab accurate (Chandra 2.7) | 94.4 | 92.0 | 95.3 | 96.1 |
| Datalab accurate (Chandra 2.6) | 94.1 | 92.0 | 94.2 | 96.0 |
| Datalab balanced (Chandra 2.7) | 93.5 | 90.1 | 94.2 | 96.1 |
| Gemini 3.8 Flash* | 92.9 | 91.3 | 95.2 | 92.2 |
| Datalab balanced (Chandra 2.6) | 92.6 | 90.1 | 91.6 | 96.2 |
| GPT-6.1 Sol | 91.5 | 89.8 | 95.6 | 89.1 |
| Reducto | 90.8 | 85.4 | 91.2 | 95.8 |
| LlamaParse | 90.4 | 88.2 | 92.6 | 90.4 |
| Claude Opus 5.5* | 90.0 | 93.9 | 93.4 | 82.6 |
| Mistral OCR | 89.5 | 82.8 | 91.9 | 93.8 |
| Claude Sonnet 5.5* | 88.7 | 93.1 | 95.4 | 77.5 |
| GPT-5.6 Sol | 87.8 | 85.4 | 91.6 | 86.5 |
* Used in creating and verifying at least some tests. † Gemini 4 rows use a rerun of the pages that failed on the first pass; see the run notes. Chandra 2.7 scores are a run of the production API on November 12, 2026. Chandra 2.6 and every other row are from the OmniParseBench results, on the same 16,288 tests. Overall is the mean of the unrounded text, tables and layout scores.
Text and layout scores are about the same as Chandra 2.6. Datalab accurate scores 94.4, behind only Gemini 4 Argon and Carbon. Datalab balanced now scores above Gemini 3.8 Flash.
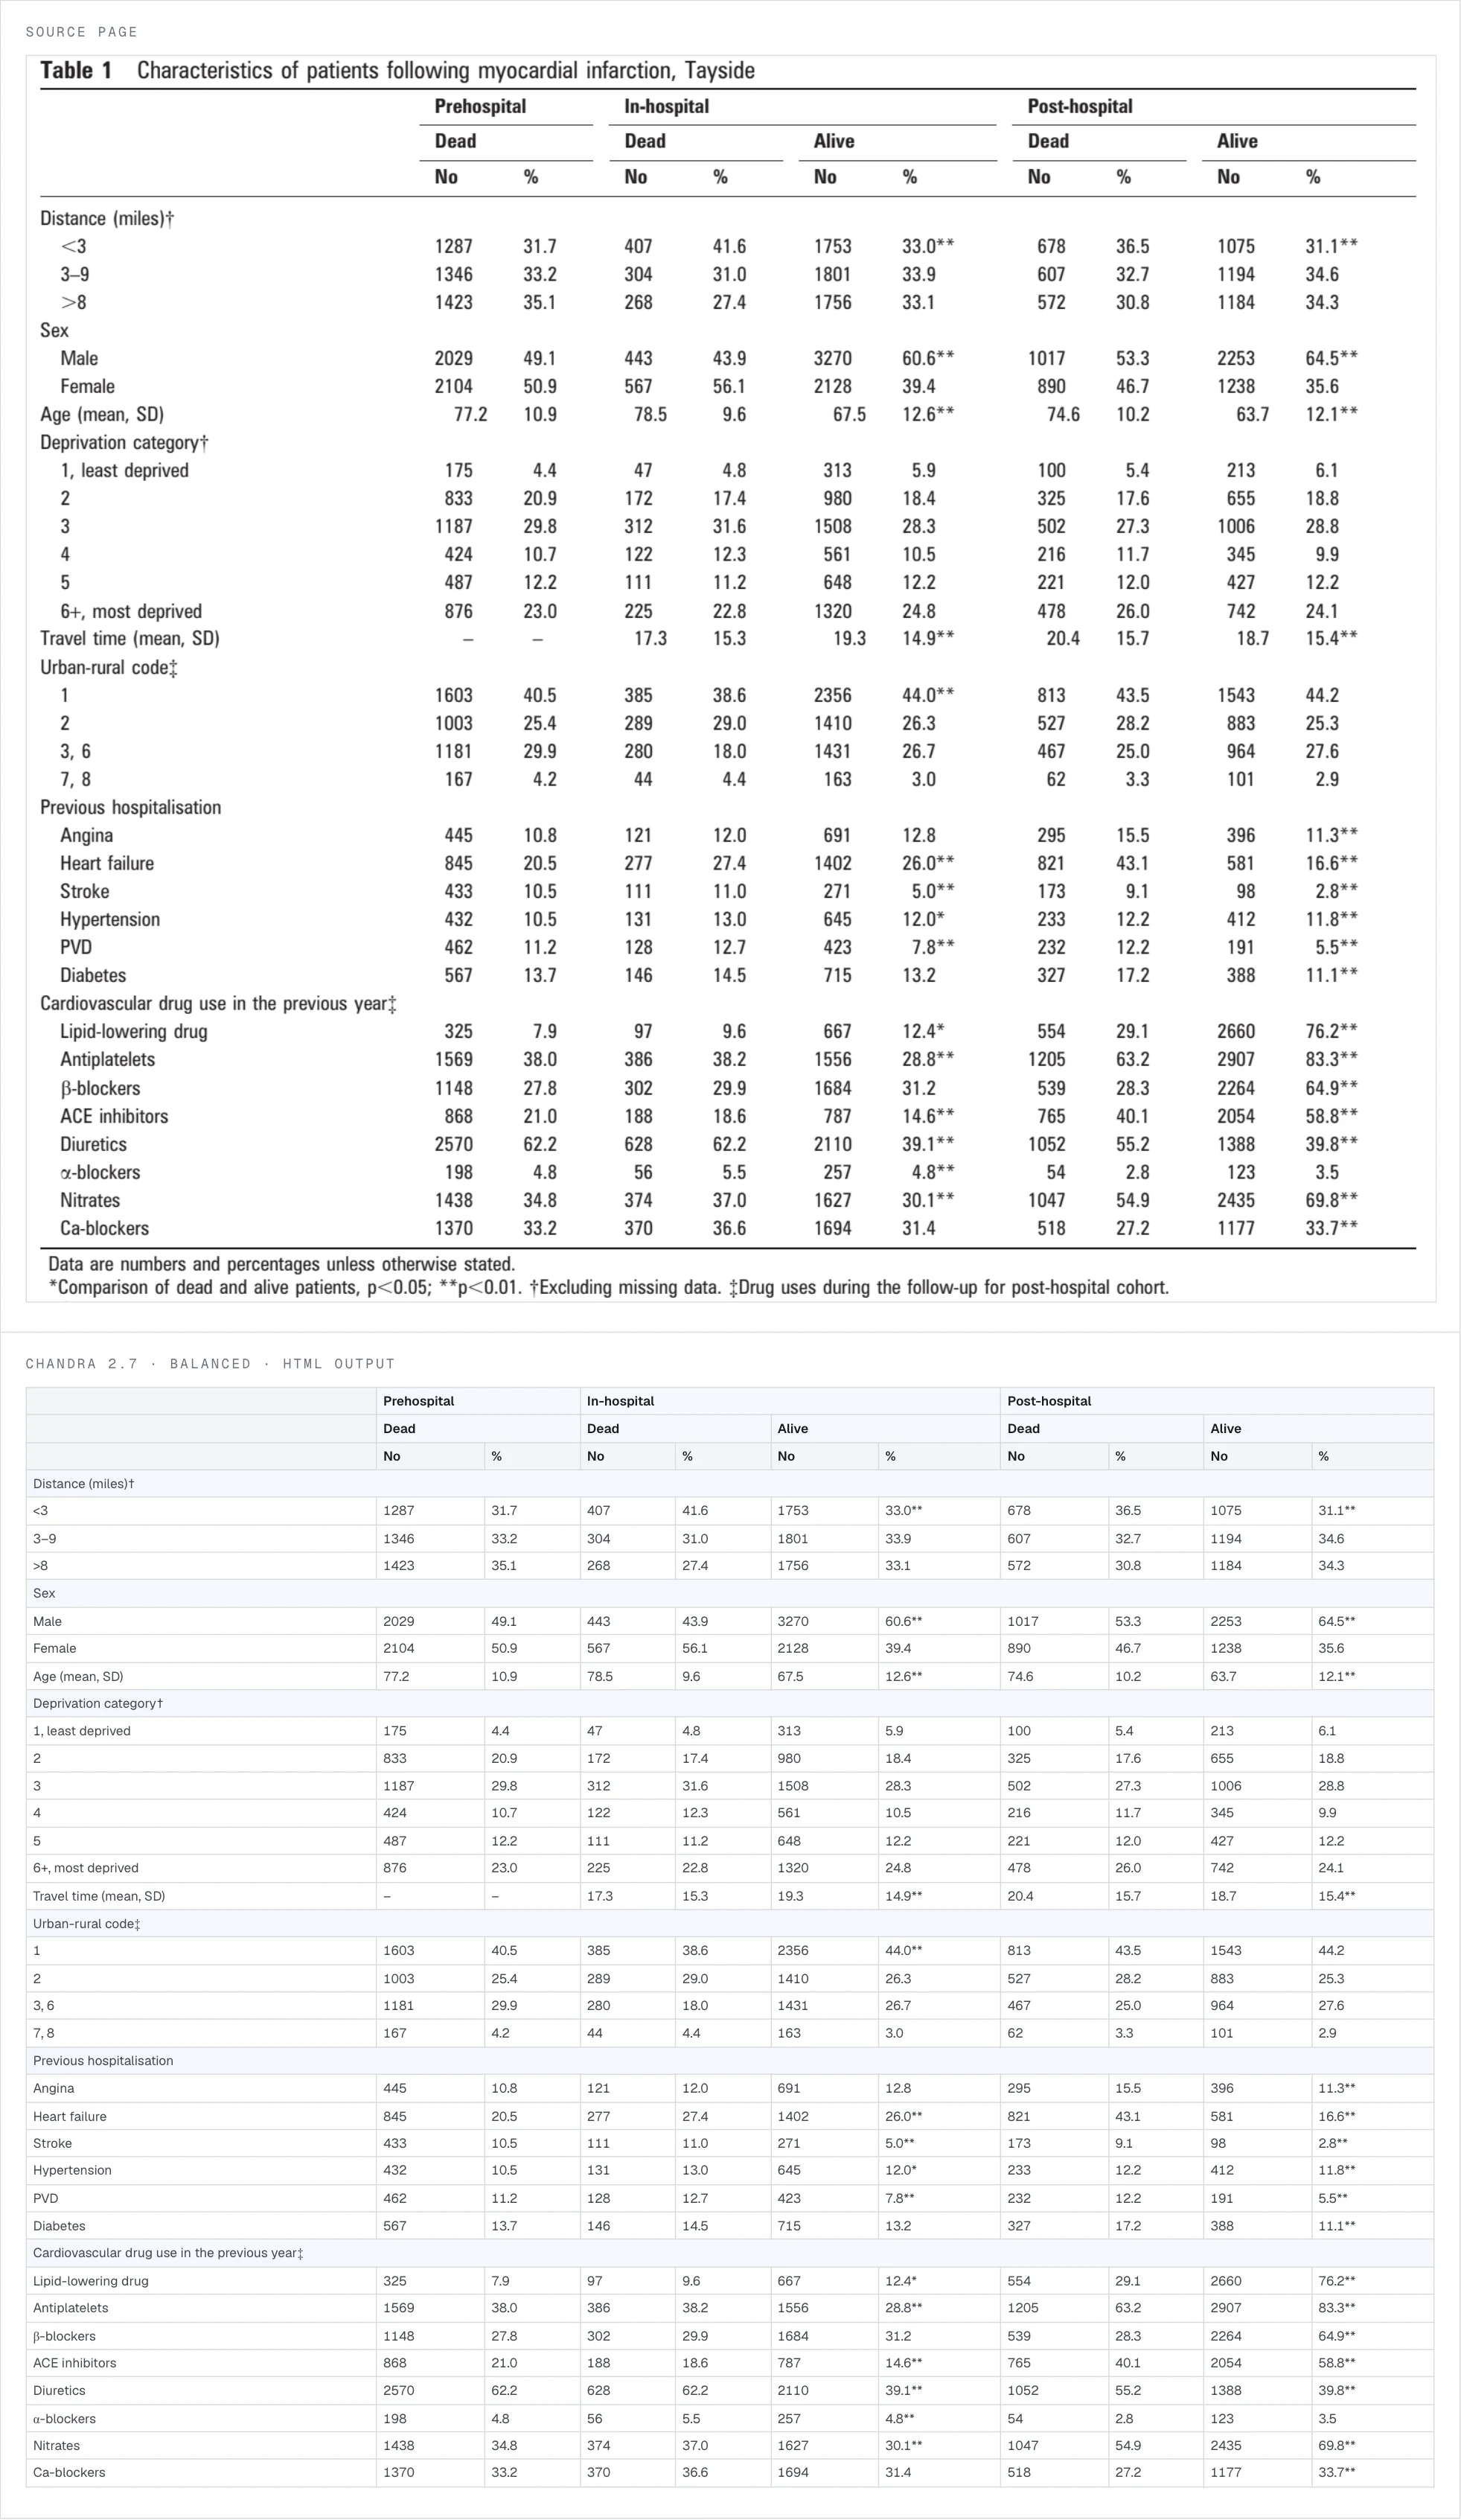
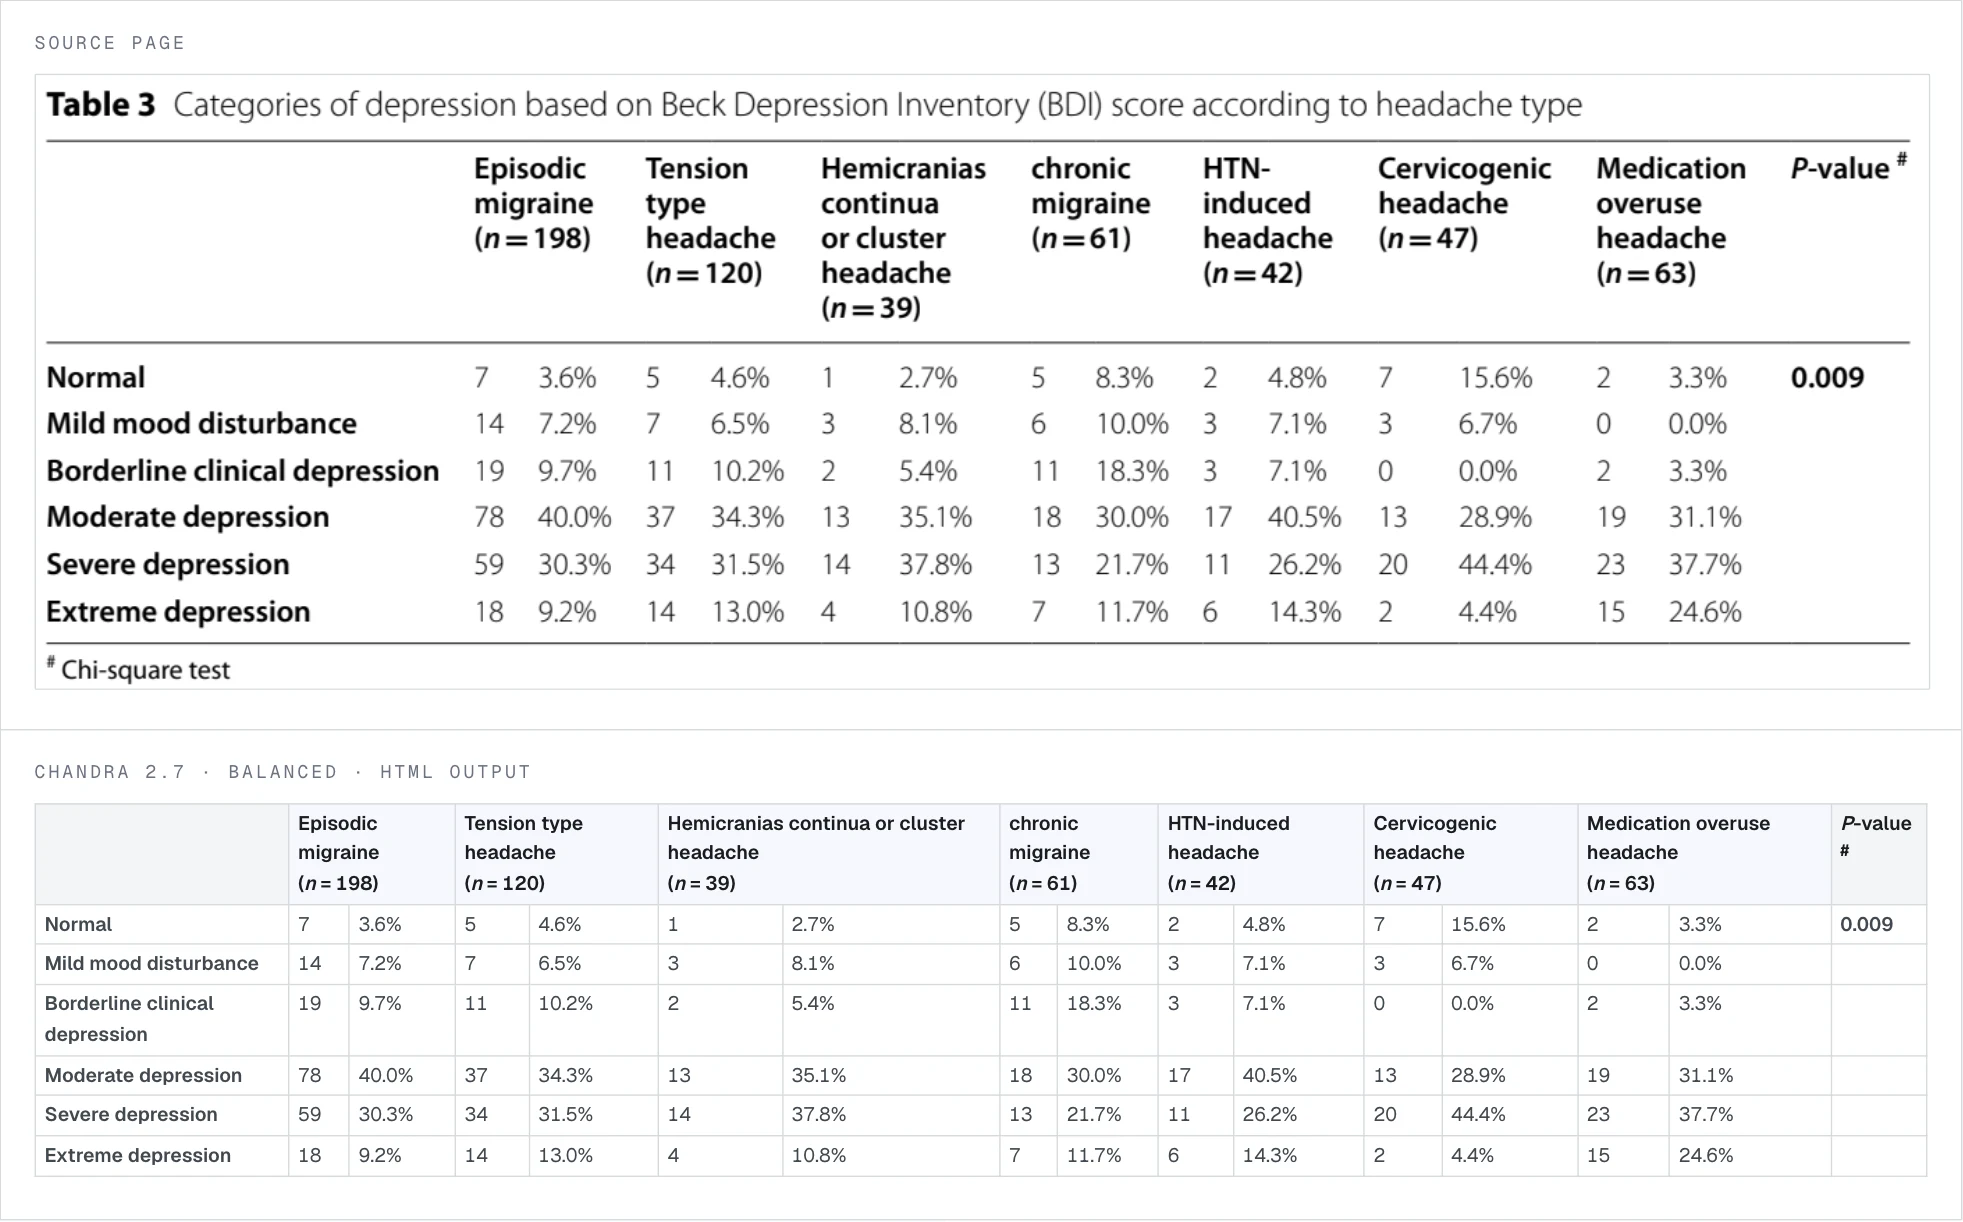
Here are two OmniParseBench tables that Chandra 2.6 got wrong in both modes, and that Chandra 2.7 gets right.
The first has three levels of column headings. Chandra 2.6 read every value, but put the In-hospital and Post-hospital columns under the wrong headings, so all 12 of the page’s table tests failed. Chandra 2.7 passes all 12:
In the second, none of the percentages Chandra 2.6 returned were in a table cell of their own, so none of the 12 table tests passed. Chandra 2.7 gives each count and percentage its own cell:
Better on non-English pages
OmniParseBench covers 92 languages. On its non-English pages, 87.9% of tests pass in accurate mode, up from 86.7% with Chandra 2.6. Balanced mode is about the same, at 83.0%, up from 82.7%.
Tests whose language tag is not English: 1,935 tests on 534 pages, the same tests for both models. Scores for tagged pages here and below are the share of their tests that pass.
Where Chandra 2.7 got better
- Rotated pages: 87.3% of tests pass in balanced mode, up from 81.4%.
- Pages that contain tables: 94.7% in balanced mode, up from 92.3%, and 95.7% in accurate mode, up from 94.6%.
- Forms: 90.8% in balanced mode, up from 88.9%, and 93.7% in accurate mode, up from 92.3%.
- Tiny text: 95.2% in accurate mode, up from 93.6%.
Where Chandra 2.7 is not better
Math pages score about 1 point lower: 93.2% of tests pass in accurate mode, down from 94.1%, and 92.6% in balanced mode, down from 93.6%. Degraded scans are about 1 point lower too. Multi-column pages score about the same.
Same speed and price
Chandra 2.7 is as fast as Chandra 2.6. The price stays the same: balanced is $4 per 1,000 pages ($3 with data sharing), and accurate is $10 ($7.50 with data sharing). See pricing.
Try it
Chandra 2.7 is live in the API and the playground. For on-premises deployments, contact us at [email protected].
If you have hard documents you want us to try, especially tables or languages we don’t read well yet, send them to [email protected].