
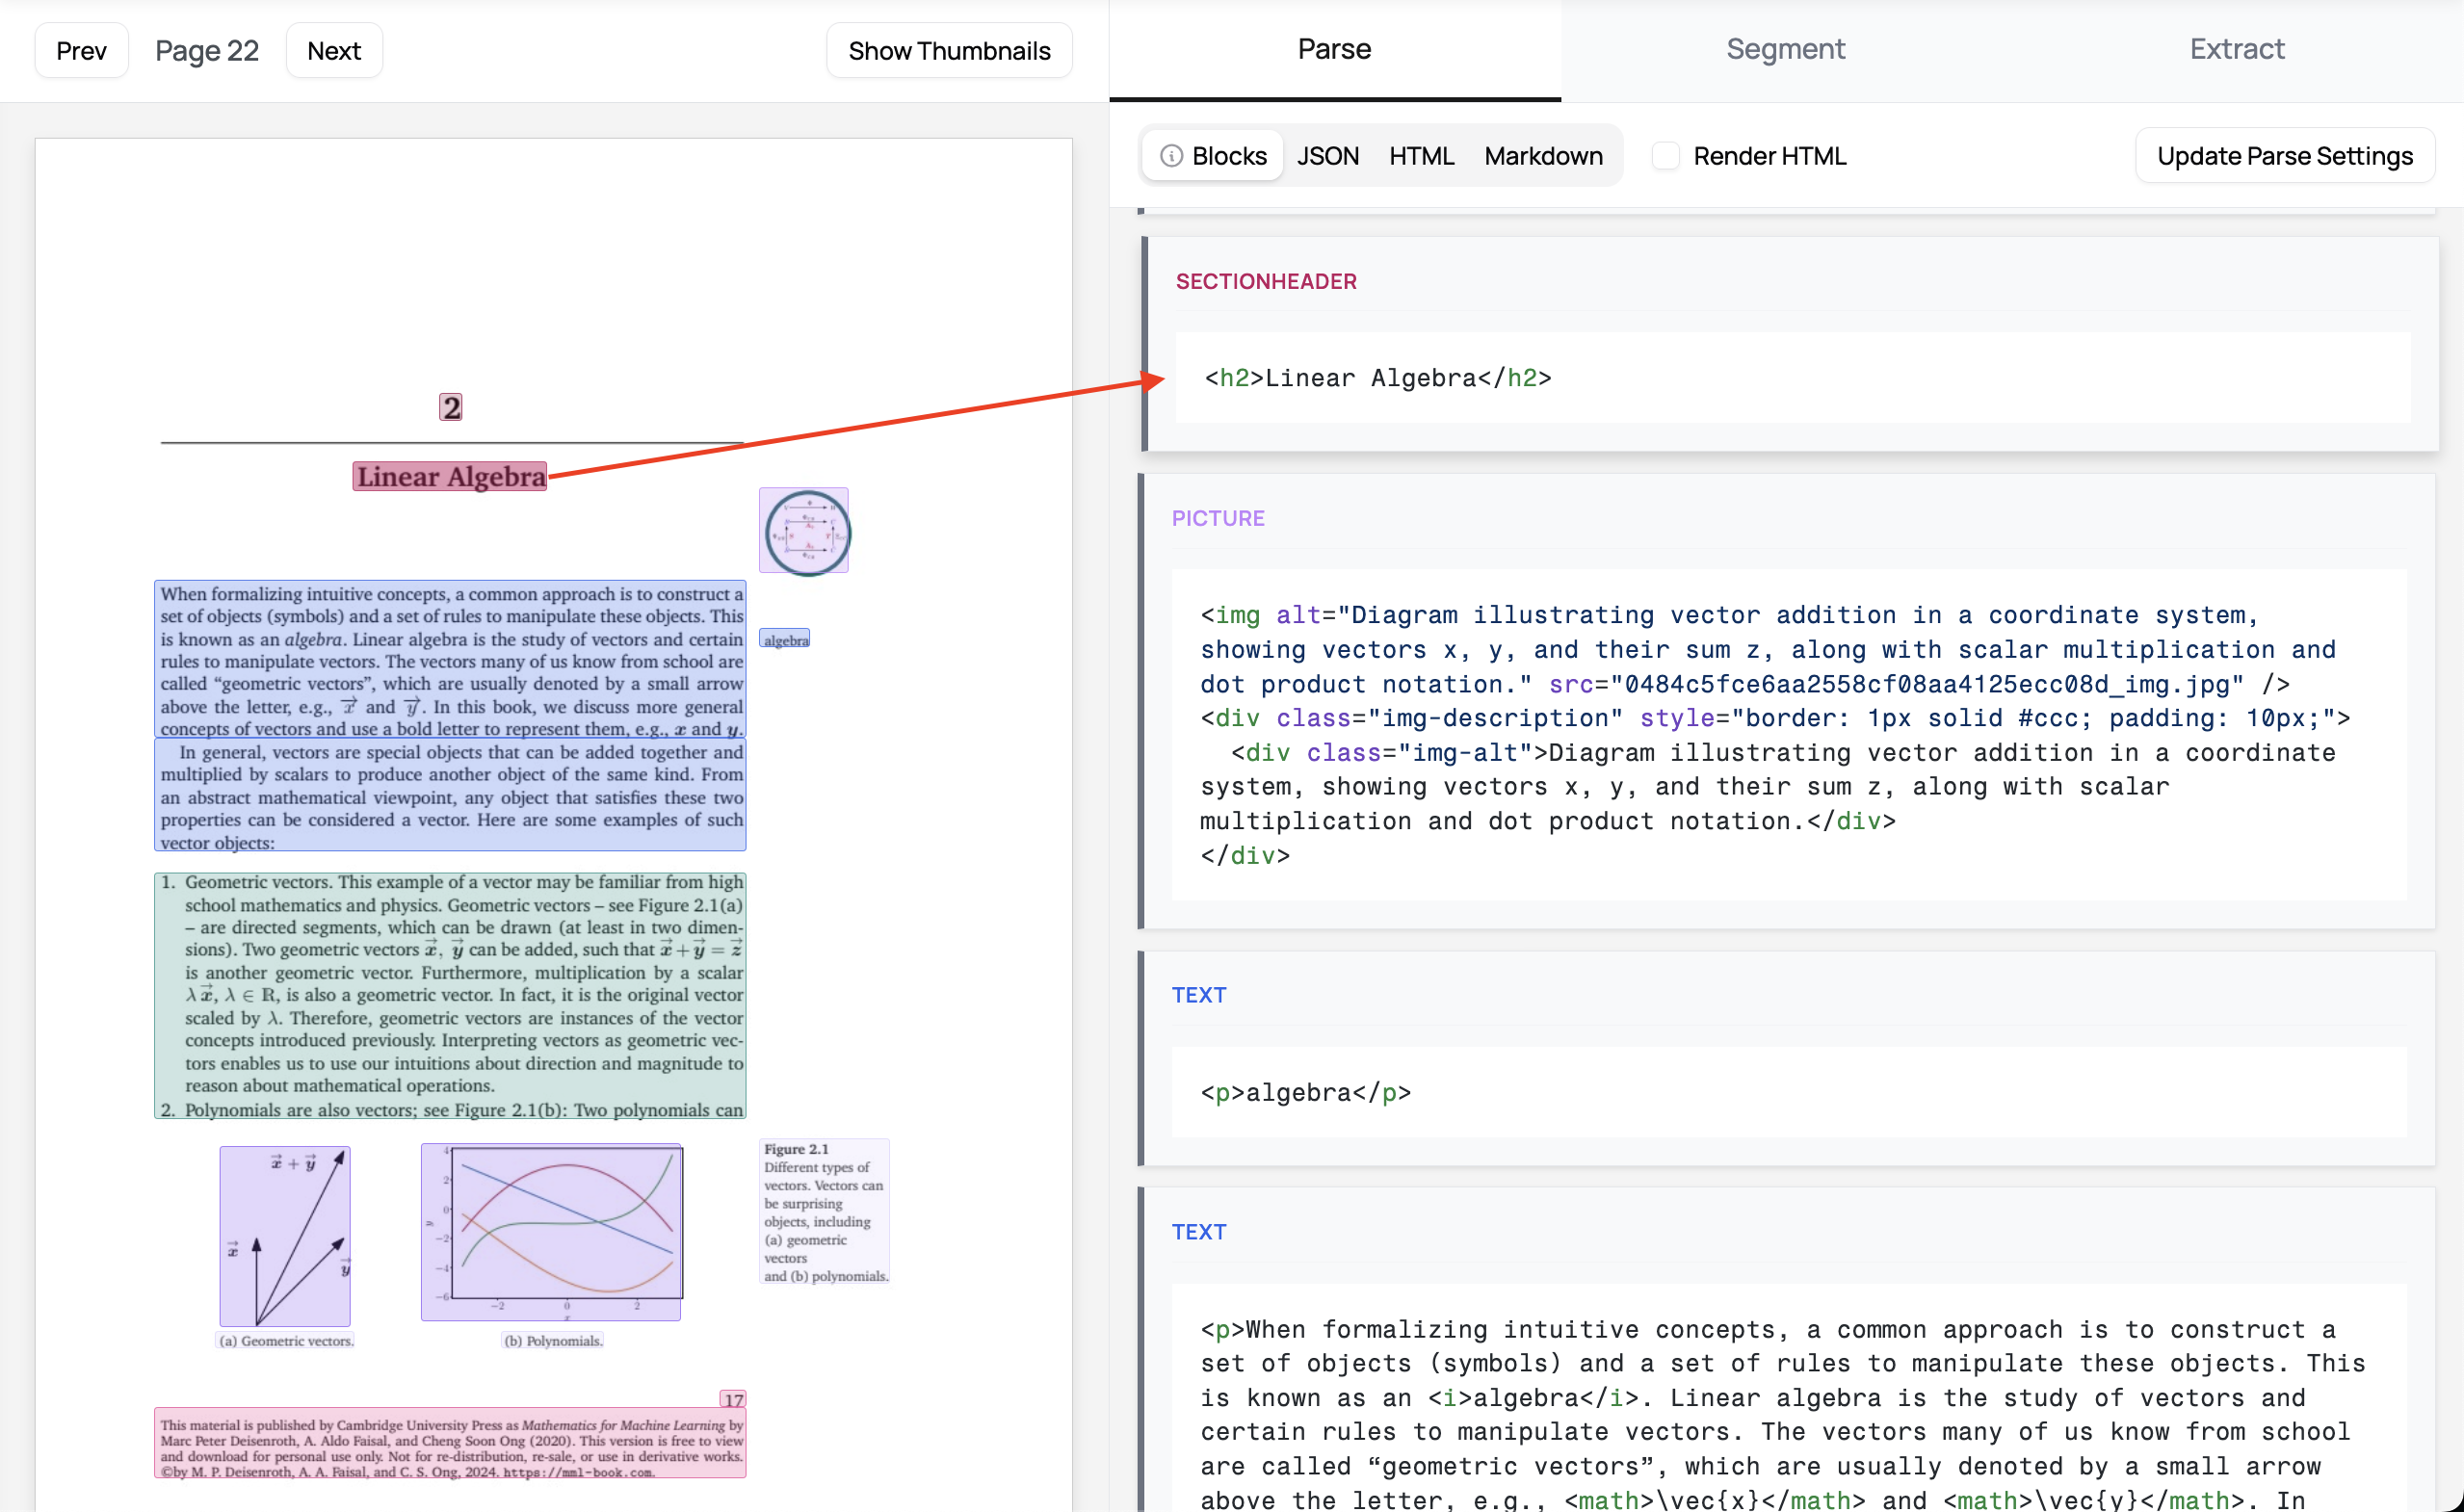
Section Hierarchy Across Long Docs
Accurately detect sections and subsections across long PDF documents
Real examples of what teams parse with Datalab — long PDFs, spreadsheets, multilingual and math-heavy documents. Filter by industry, feature, or workflow to find the one closest to yours.




Accurately detect sections and subsections across long PDF documents

Parse Spreadsheets with Multiple Tables and Empty Cells
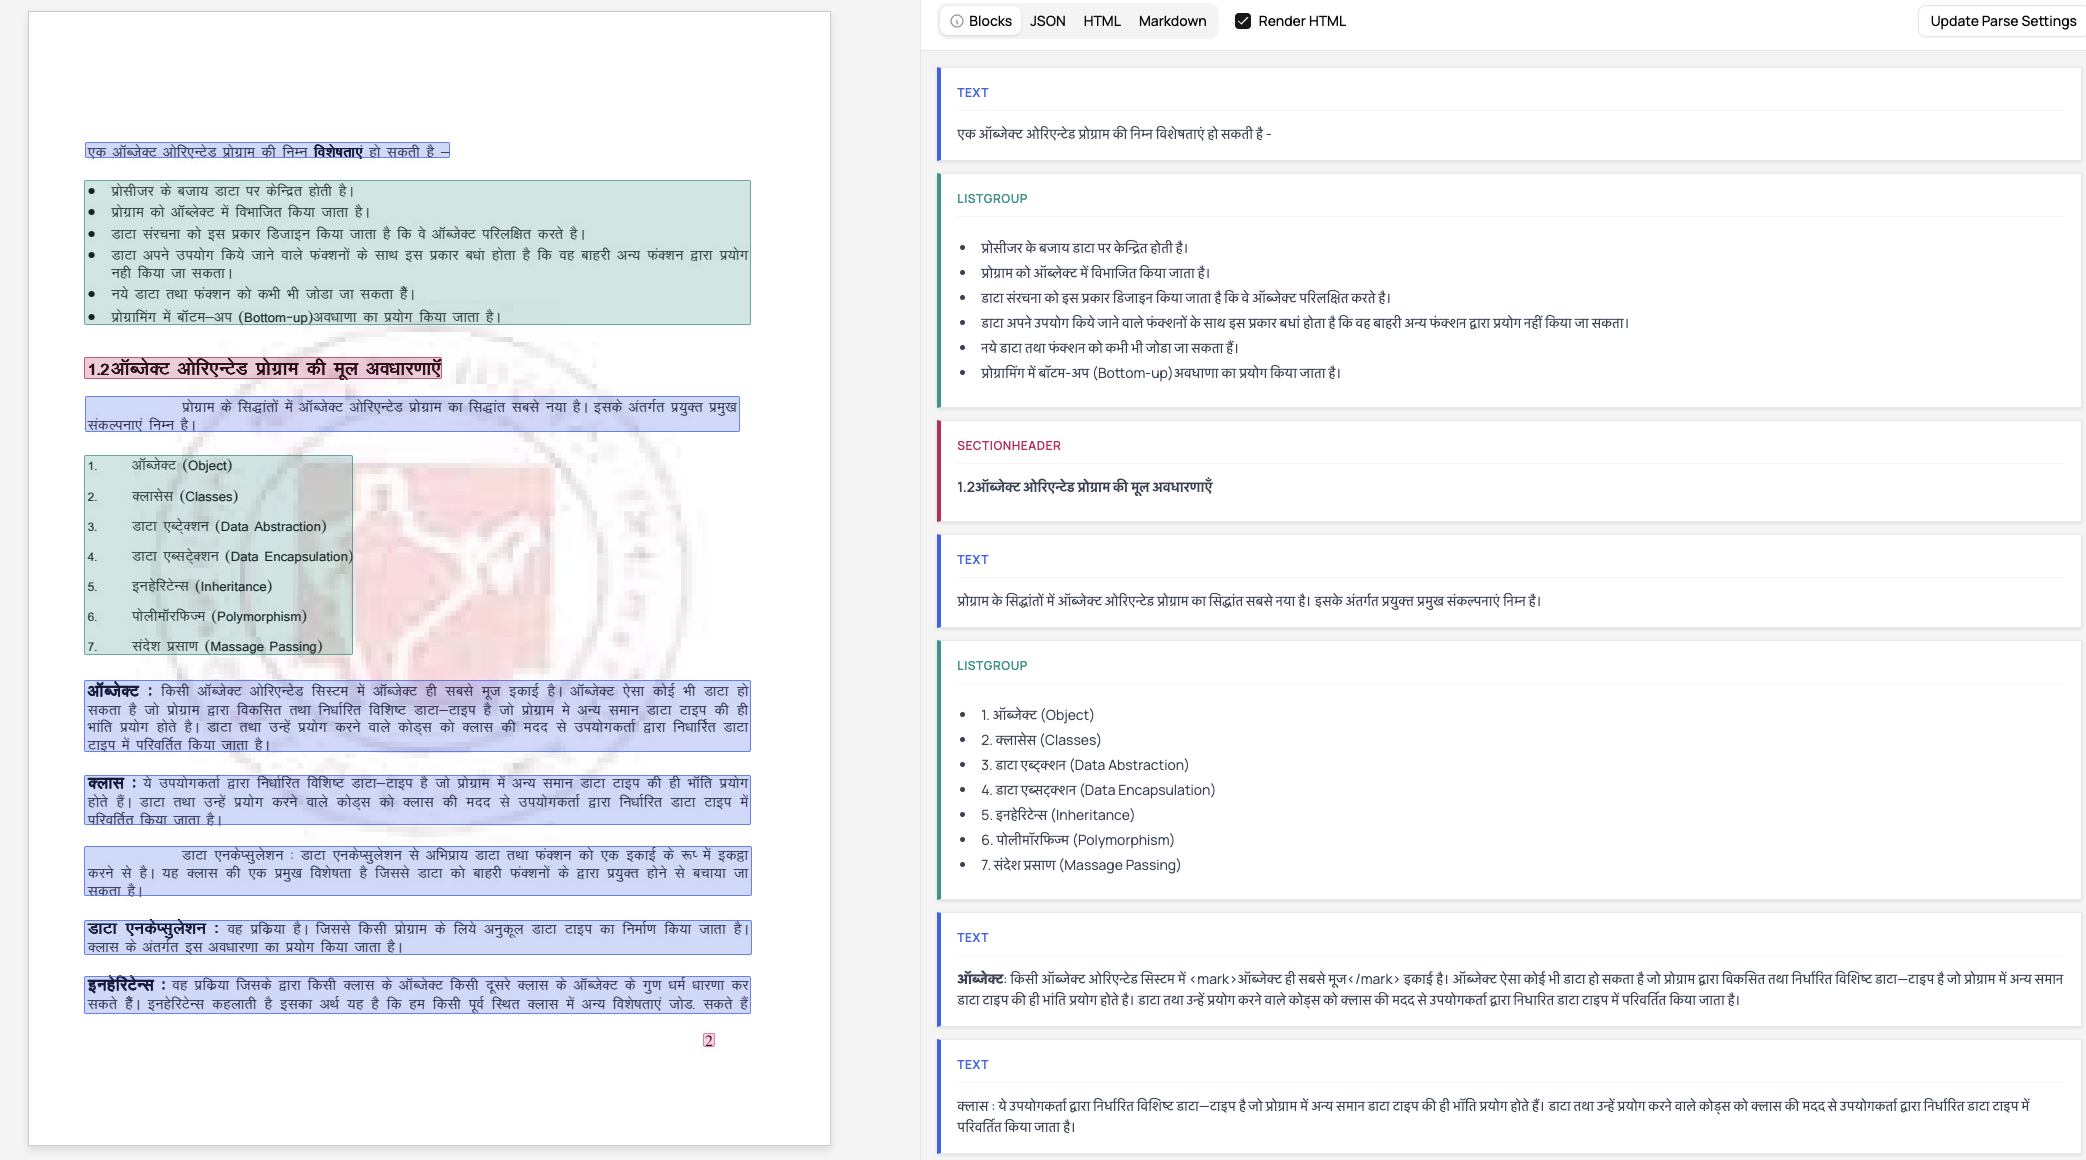
Parse and structure Hindi documents

Extract mathematical PDFs containing dense notation, equations, and references

Parse complex multi-modal scientific documents

Datalab already supports over 90 languages to enable a more global participation and representation in AI systems.
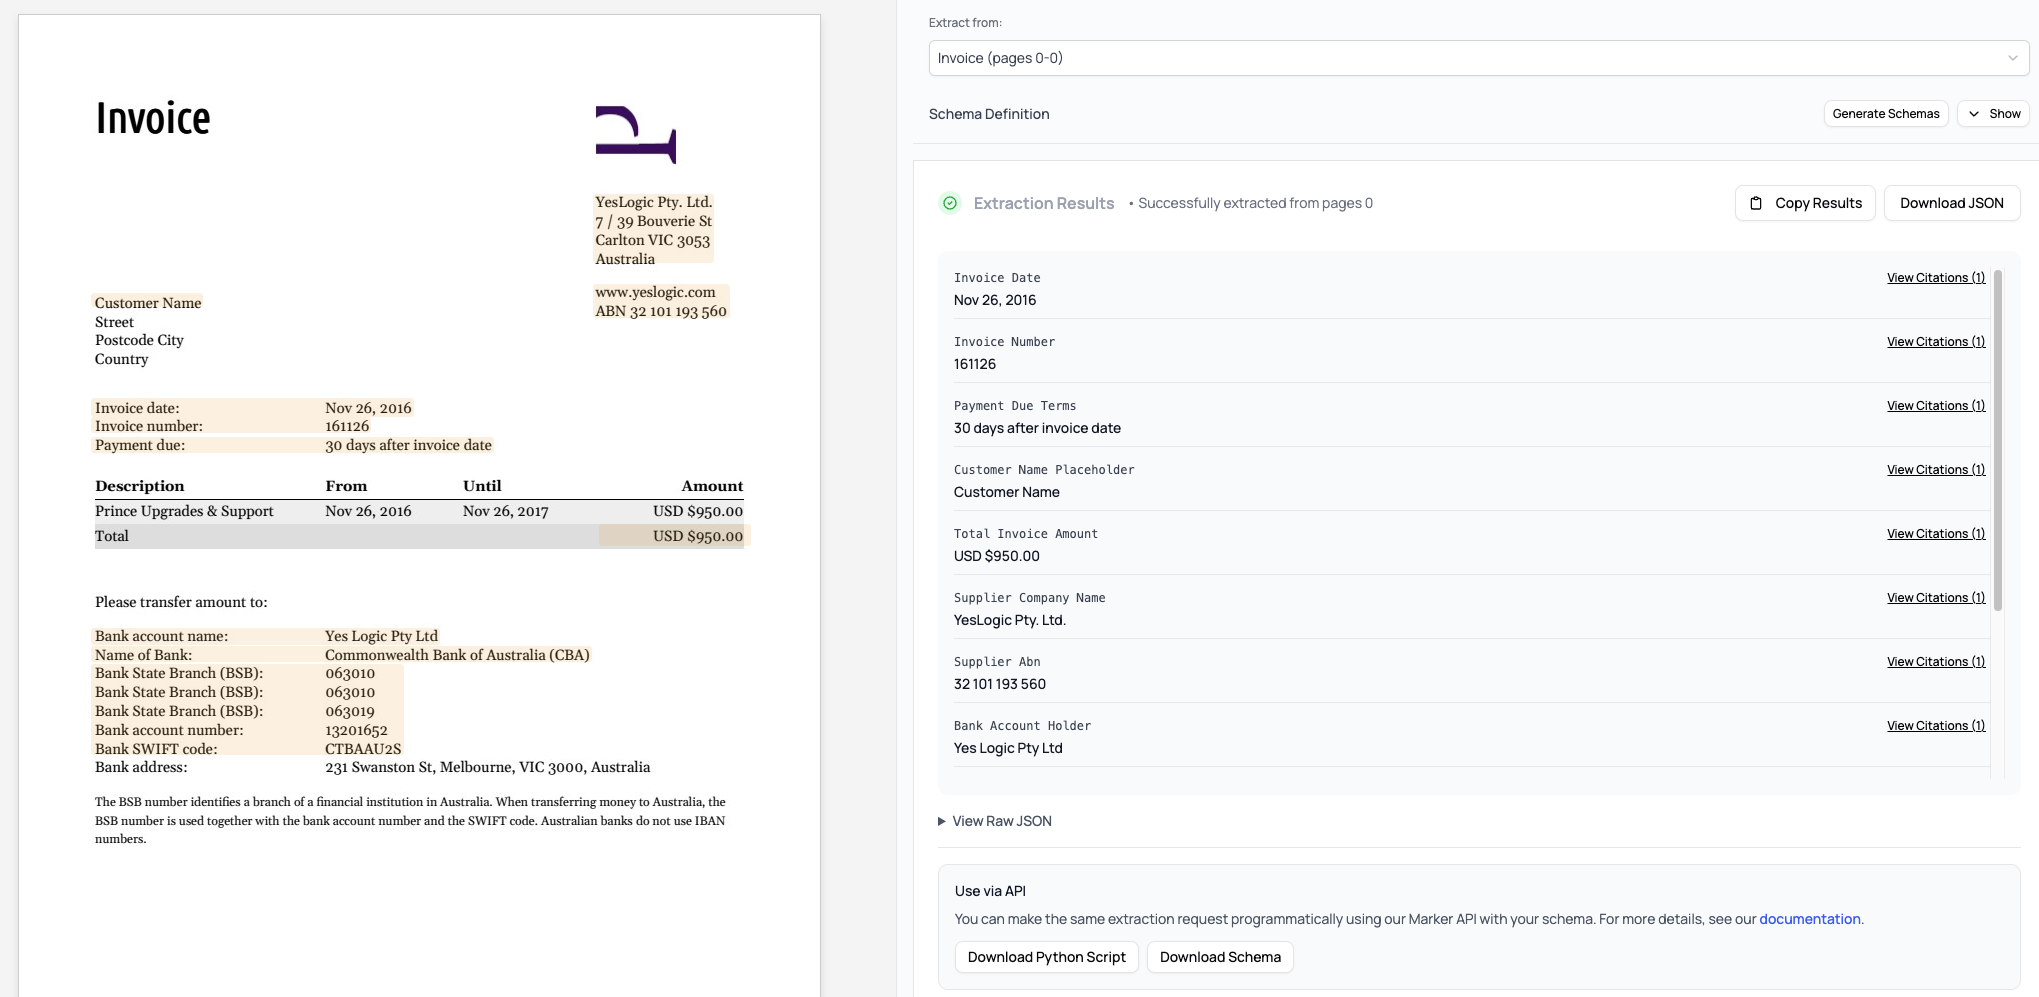
Transform invoice PDFs into structured, machine-readable formats
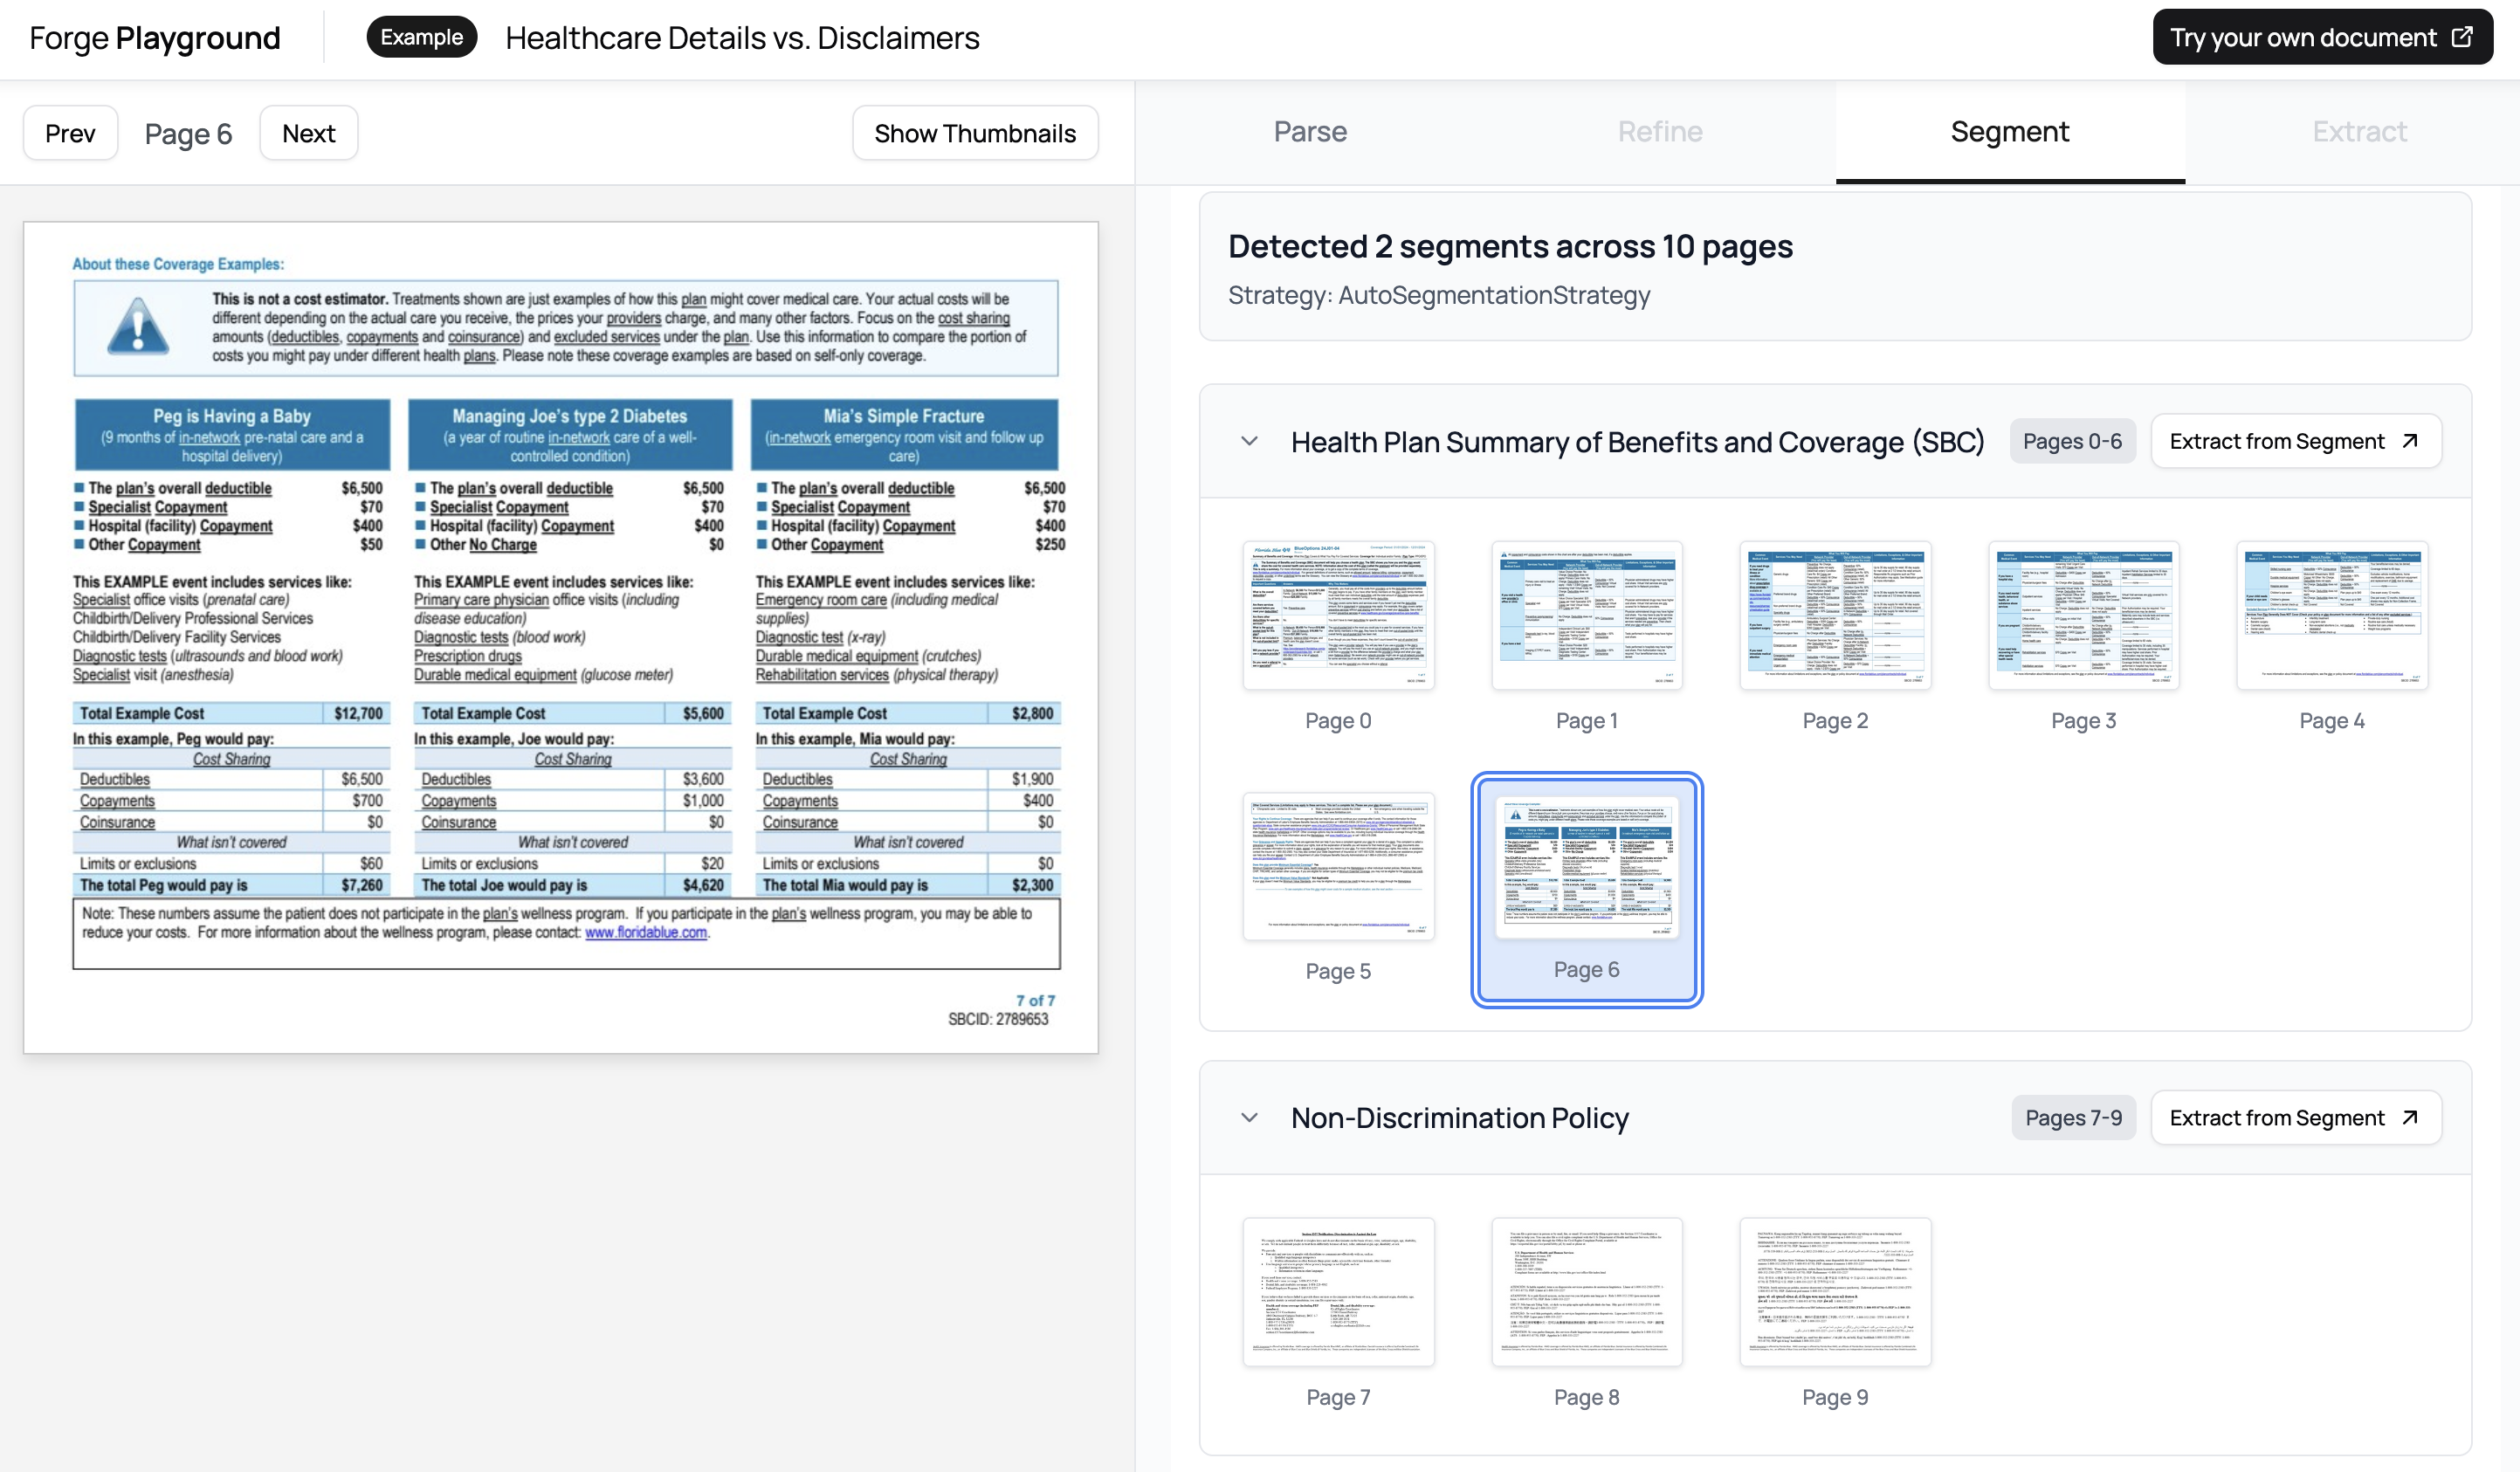
Useful tools to recover documents from 'digitally stapled' PDFs.
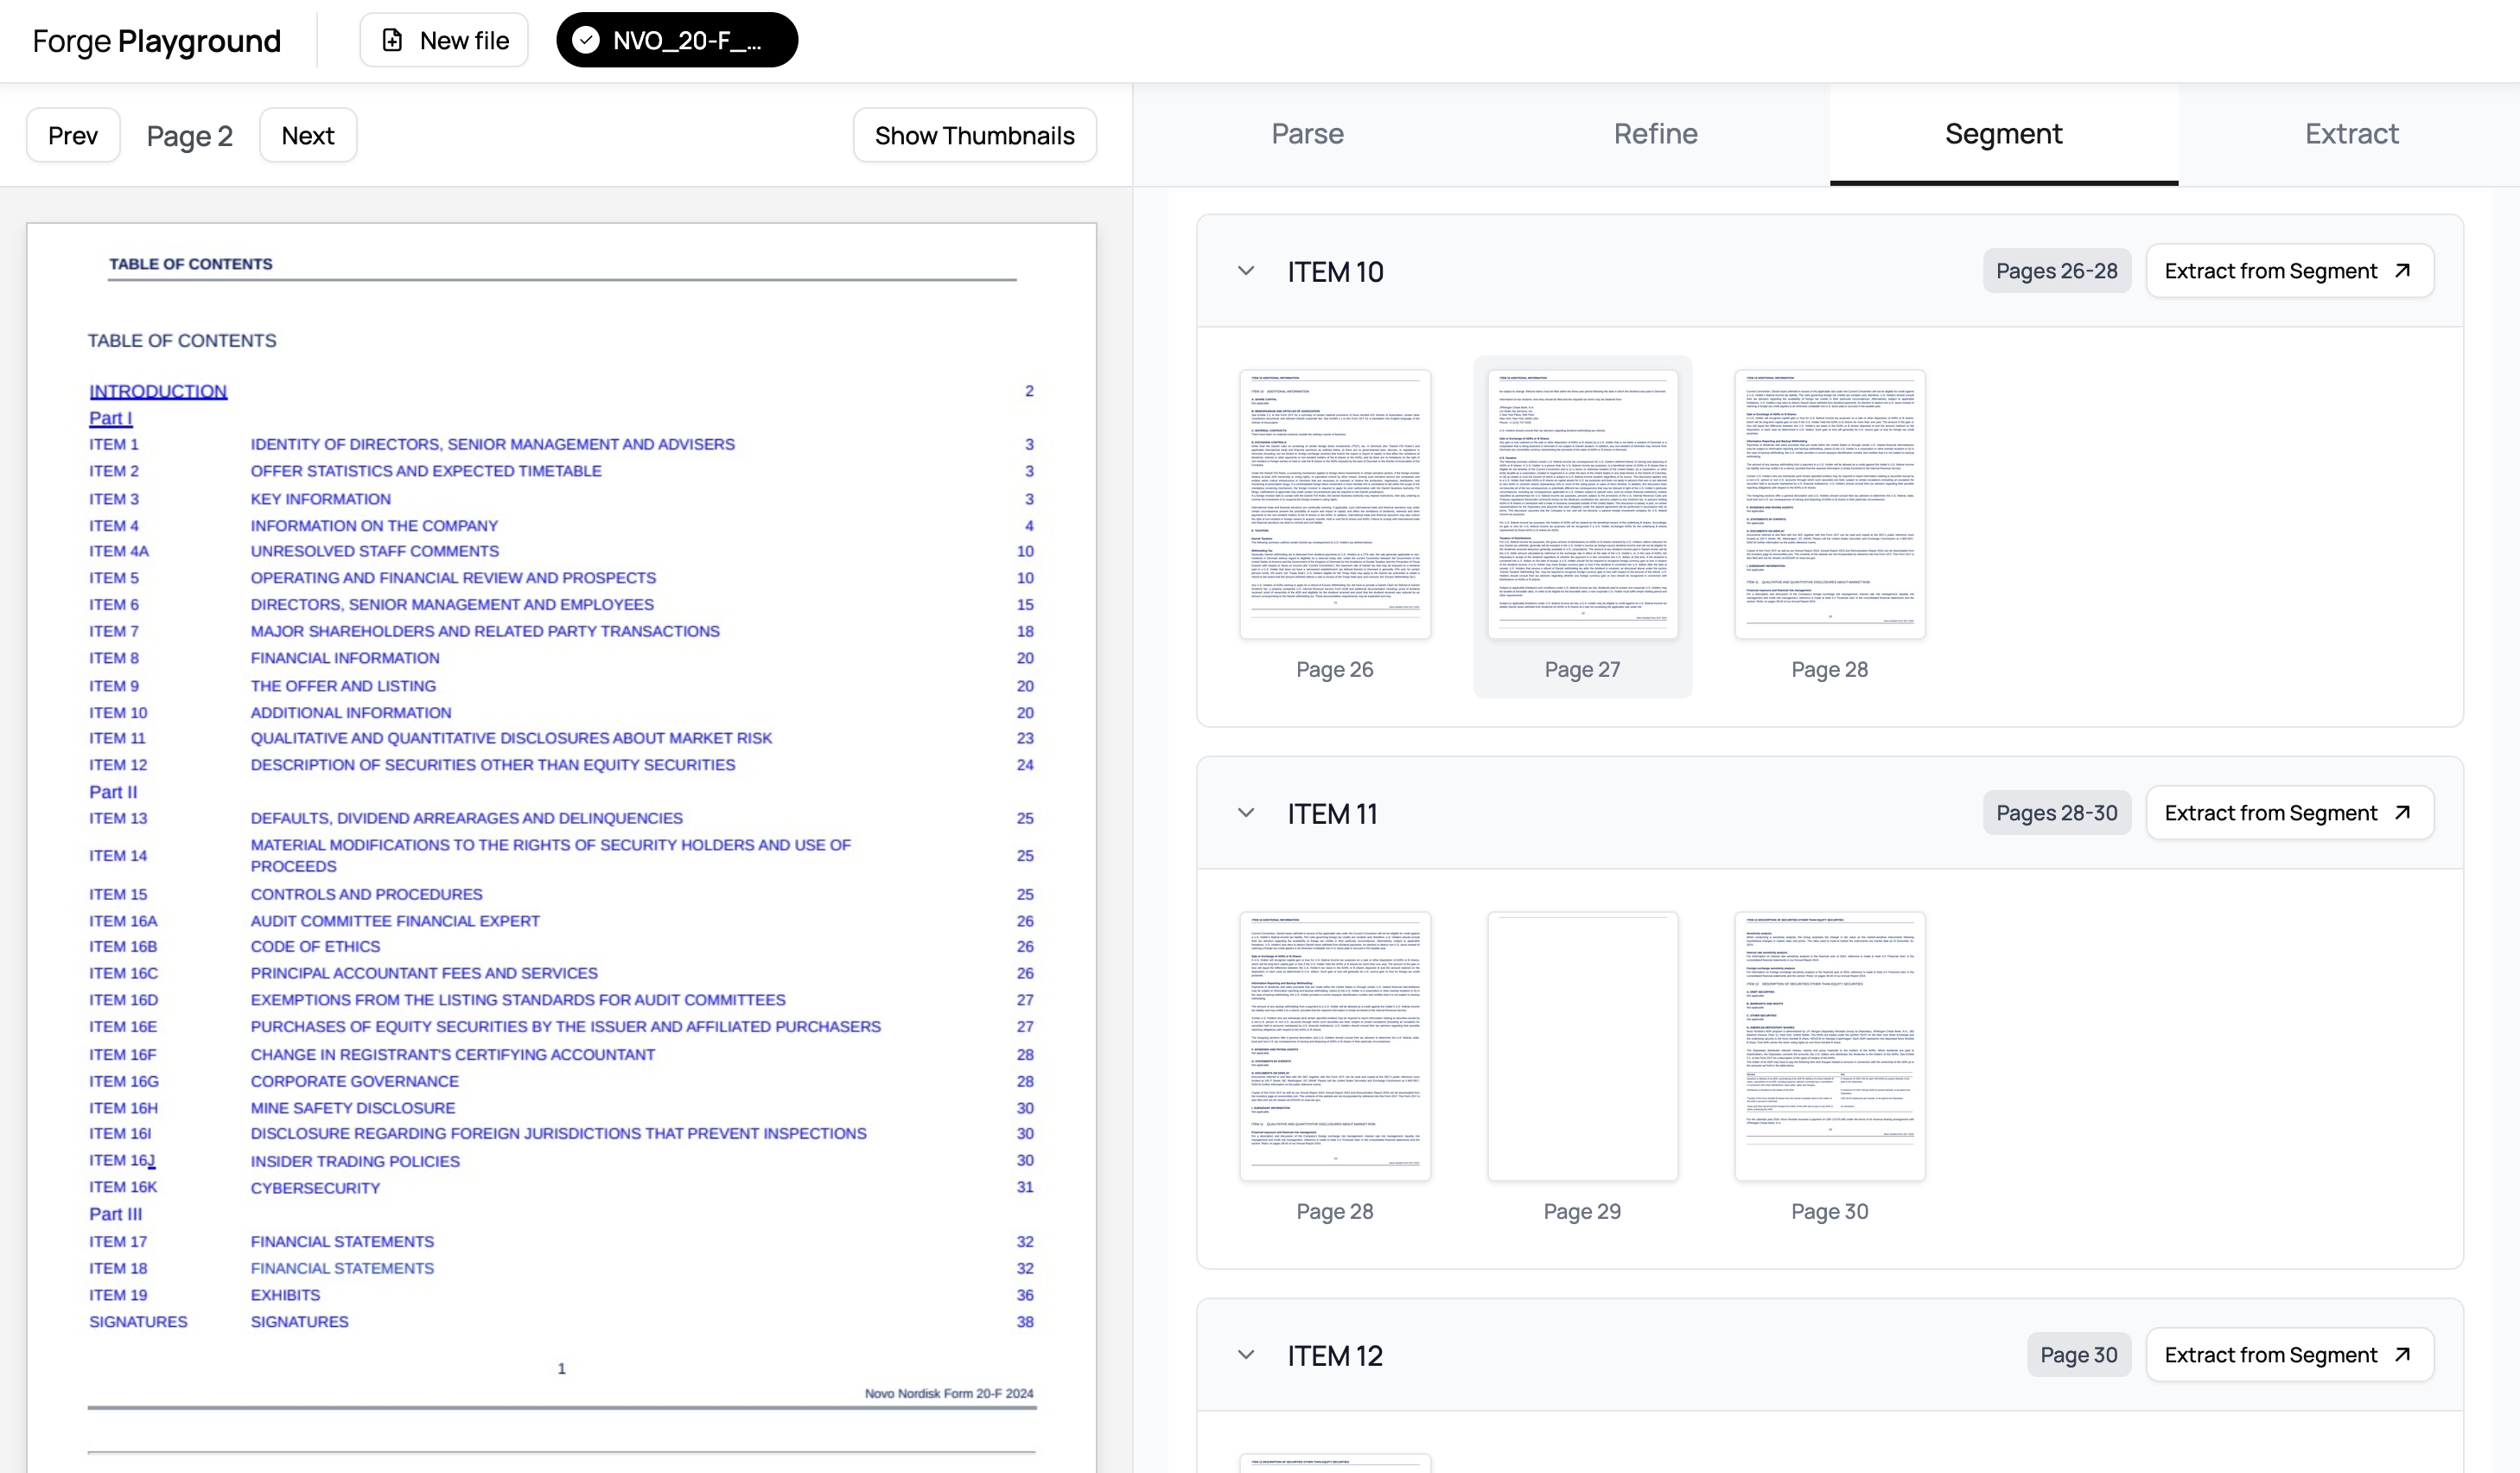
SEC filings are a rich source of financial information about companies, but can be difficult to parse at scale.
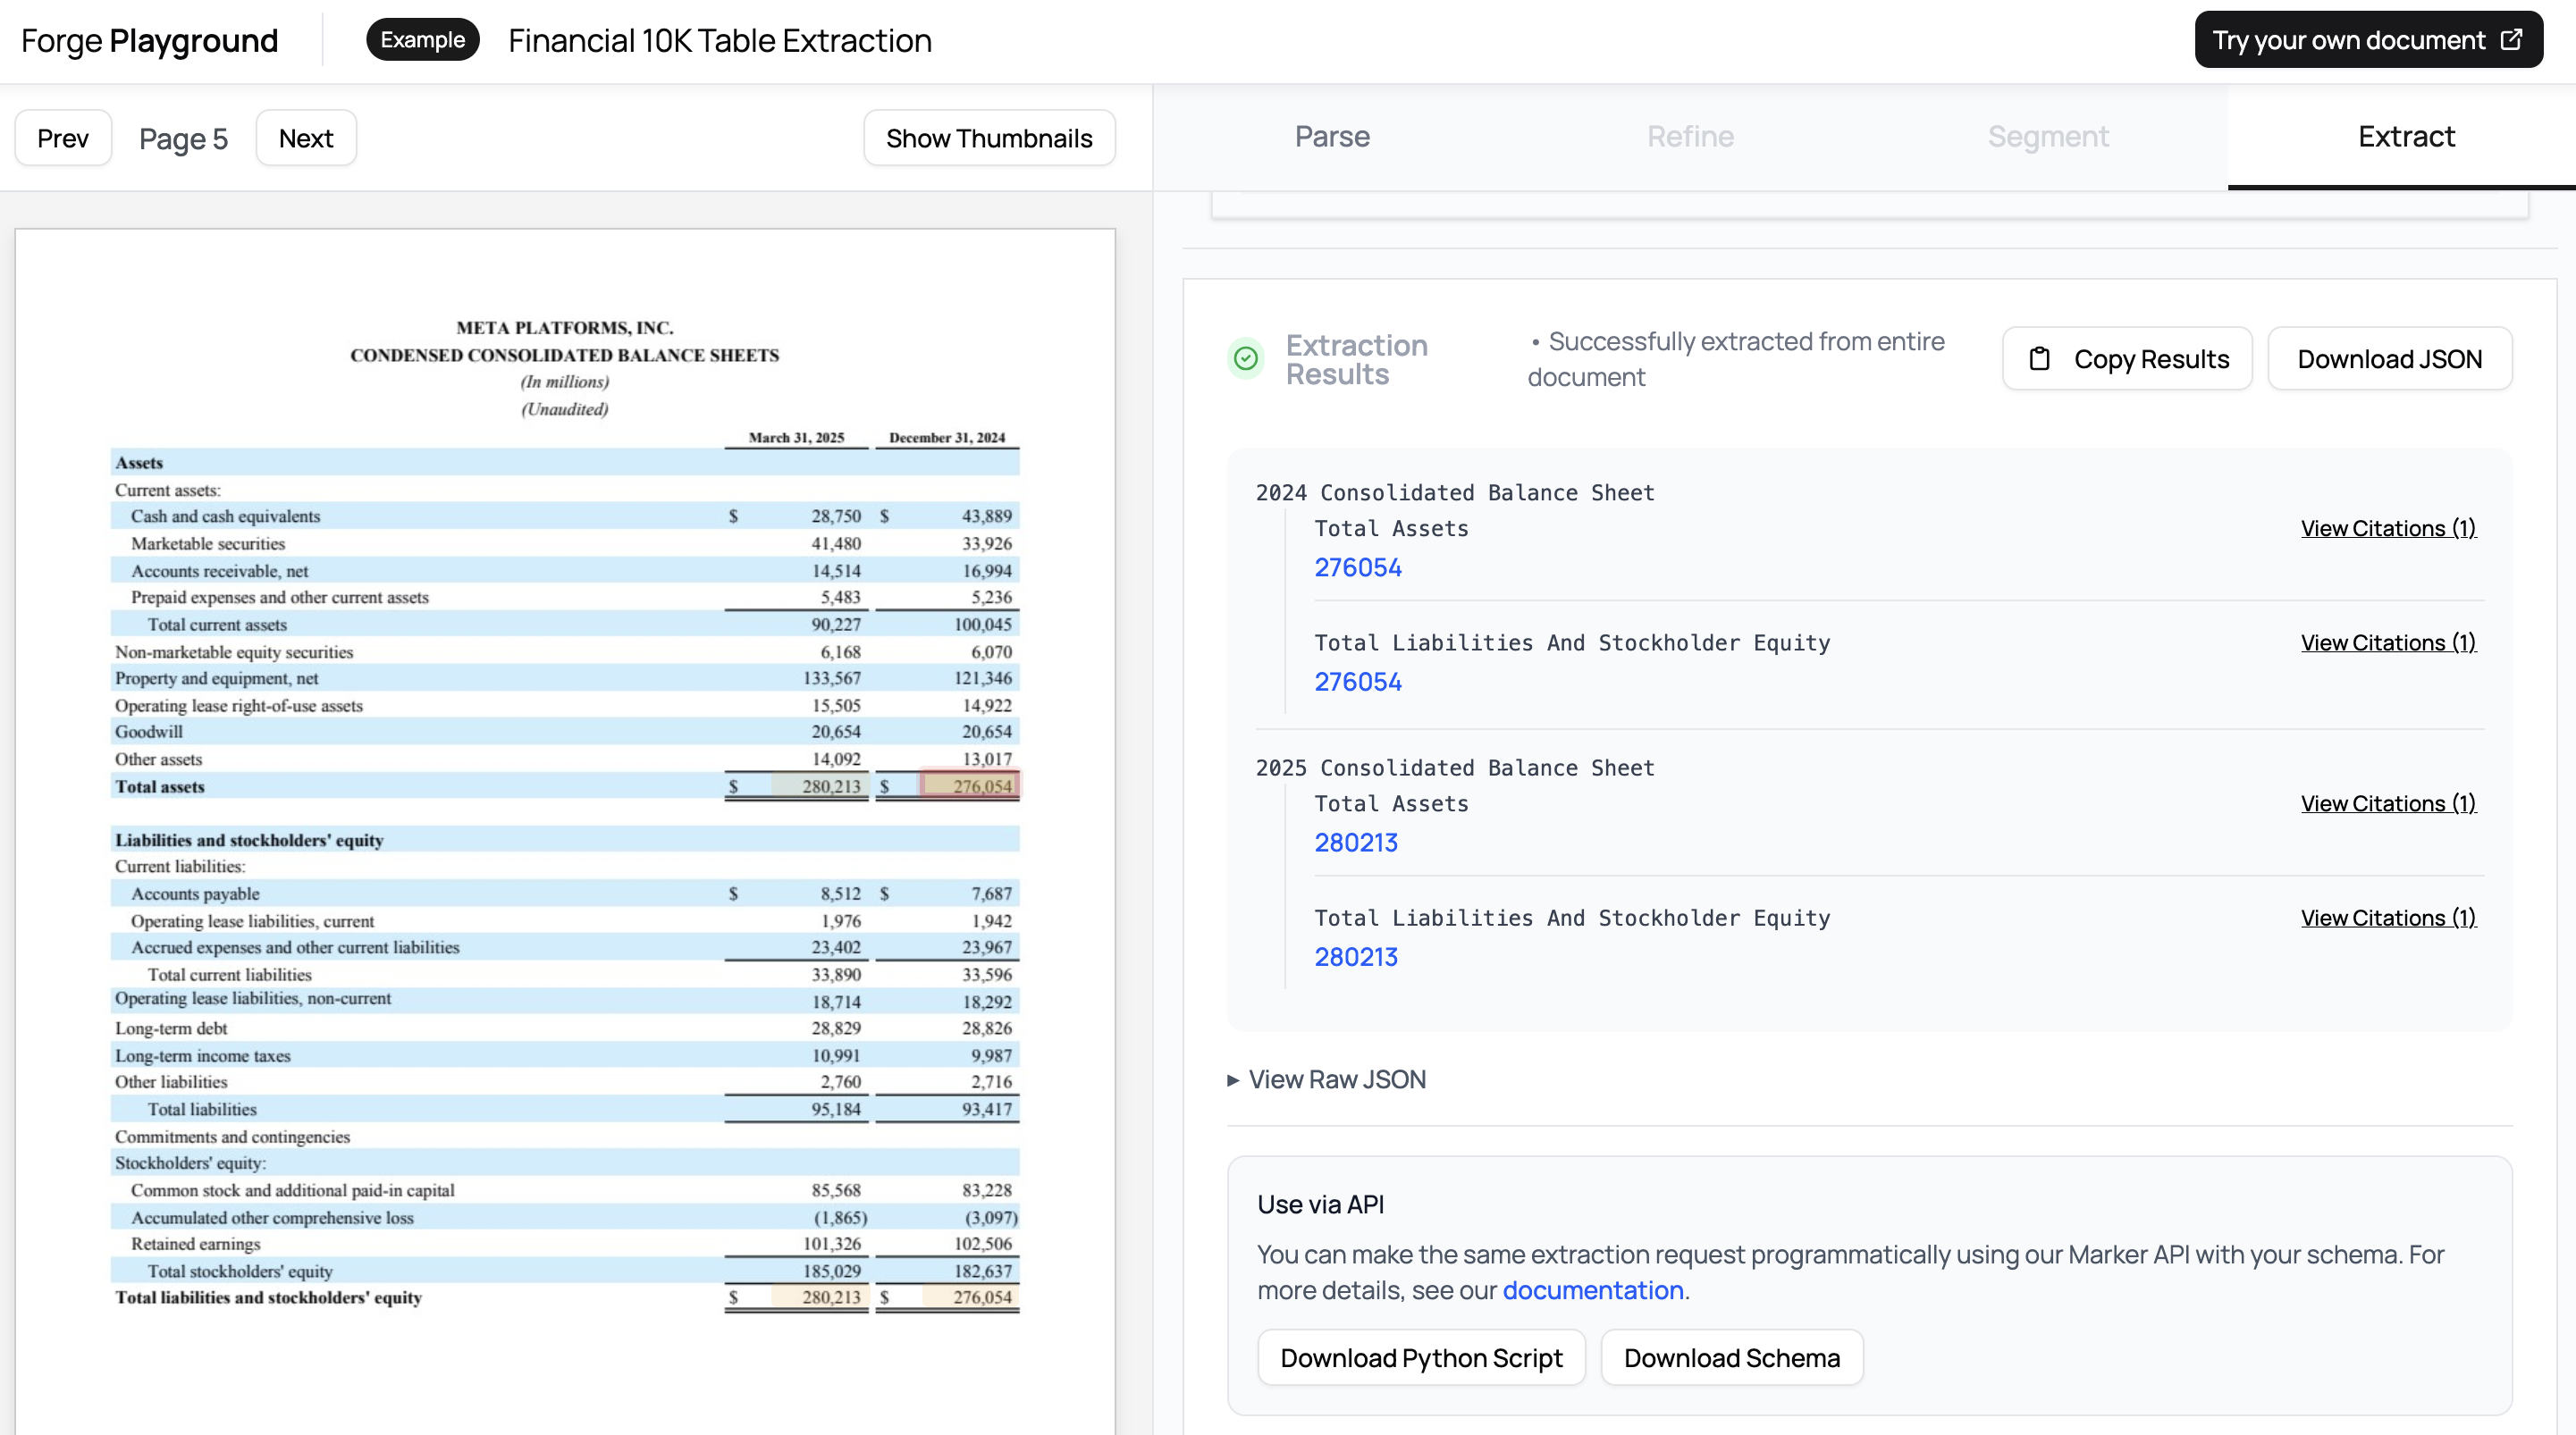
Extract key insights from SEC filings, investor decks, and more. Datalab handles complex, deeply nested tables, cross-page content, and more.
Free tier. No credit card. SOC 2 Type II.