# Chandra 2.5: Structured Image Descriptions and Faster OCR
> Chandra 2.5 is live in the Datalab API. Every figure gets the same structured description, and every mode is faster: 40-43% lower median latency.
- Canonical: https://www.datalab.to/blog/chandra-2-5
- Published: 2026-10-14
- Authors: Vik Paruchuri
Chandra 2.5 is available today in the Datalab API, and every mode (fast, balanced and accurate) runs on it. You don't need to change anything to use it.
Here's what changed, compared with Chandra OCR 2.4, the model it replaces:
- **Image descriptions in one fixed format.** Every chart, diagram and photo comes back with the same six fields, including chart values and verbatim text from inside the figure. In `json` and `chunks` output they're in a new `image` field.
- **38% fewer loops.** Chandra 2.5 loops 38% less often than Chandra OCR 2.4 on our loop test set, and reads rotated pages better.
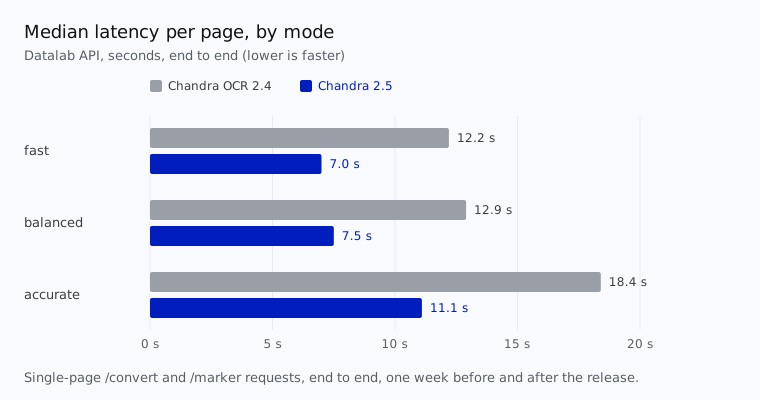
- **Faster in every mode.** Median single-page latency is 40-43% lower in every mode. In balanced mode, it went from 12.9 s to 7.5 s.
fig. 1 - Median latency per page in the Datalab API, before and after Chandra 2.5.
## Image descriptions in one format
Chandra OCR 2.4 described each figure in free text: an `alt` attribute and a block of prose, with no fixed fields. So the shape of the output changed from figure to figure.
Chandra 2.5 writes every figure in one structure, always in the same order:
| Field | When | What it holds |
| ------------- | ----------------------------- | ------------------------------------------------------------------- |
| `alt` | Always | "Kind: subject." in at most 20 words |
| `text` | The figure has other text | Text inside the figure that isn't in `axes` or `data`, verbatim |
| `axes` | Charts | Axis titles and units, as printed |
| `data` | Charts | One HTML table per panel. Values read off an axis are marked `~` |
| `mermaid` | Diagrams with nodes and edges | The diagram as Mermaid, node text verbatim |
| `description` | Always | At most 2 sentences: what the figure shows, from visible facts only |
A field is `null` when the figure doesn't have it. Markdown and HTML output keep their current shape.
Here is a bar chart from a U.S. Department of Education report:
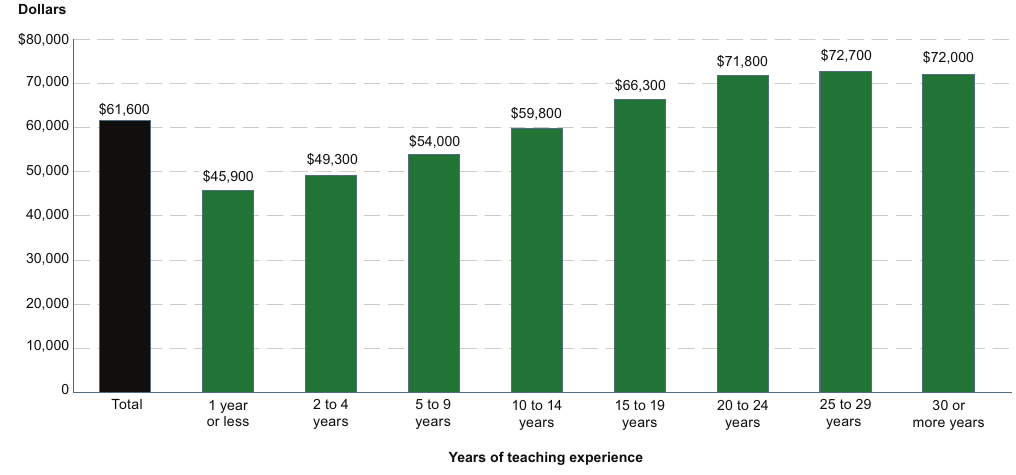
_Figure 5 from "Characteristics of Public School Teachers," [The Condition of Education 2023](https://nces.ed.gov/programs/coe/indicator/clr), National Center for Education Statistics._
Chandra 2.5, balanced mode, the `image` field:
```json
{
"alt": "Bar chart: Salary by years of teaching experience.",
"text": null,
"axes": "x: Years of teaching experience; y: Dollars, 0 to 80,000",
"data": "
Years of teaching experience
Dollars
Total
$61,600
1 year or less
$45,900
2 to 4 years
$49,300
5 to 9 years
$54,000
10 to 14 years
$59,800
15 to 19 years
$66,300
20 to 24 years
$71,800
25 to 29 years
$72,700
30 or more years
$72,000
",
"mermaid": null,
"description": "A vertical bar chart showing salary in dollars across different categories of years of teaching experience, with the total highlighted in black and individual experience ranges in green."
}
```
Every value matches the chart, including the small dip after 25 to 29 years. Code can depend on this shape: read `data` for chart values, `mermaid` for diagrams and `text` for labels, and skip the prose.
To get the field:
```python
import time
import requests
API_KEY = "YOUR_API_KEY"
headers = {"X-Api-Key": API_KEY}
resp = requests.post(
"https://www.datalab.to/api/v1/convert",
headers=headers,
files={"file": open("report.pdf", "rb")},
data={"mode": "balanced", "output_format": "chunks"},
).json()
while True:
result = requests.get(resp["request_check_url"], headers=headers).json()
if result["status"] == "complete":
break
time.sleep(2)
if result.get("success") is False:
raise RuntimeError(result.get("error"))
for block in result["chunks"]["blocks"]:
if "image" in block:
image = block["image"]
print(block["block_type"], image["alt"])
print(image["data"] or image["mermaid"] or image["description"])
```
## Accuracy
Chandra 2.5 is more reliable on hard pages, and it scores near the top of two public benchmarks.
**Fewer loops.** A loop is when an OCR model repeats the same line or table cell instead of moving on. On our loop test set, Chandra 2.5 loops 38% less often than Chandra OCR 2.4.
**Rotated pages.** Chandra 2.5 reads pages scanned sideways or upside down.
**OmniParseBench.** Last week we released [OmniParseBench](/blog/omni-parse-bench), an open parsing benchmark with 16,288 pass/fail tests on 2,937 pages in 92 languages. We'll report releases on it from now on. With Chandra 2.5, Datalab accurate scores 92.7 and Datalab balanced scores 91.6:
| Parser | Headline | Text | Tables | Layout |
| ----------------- | -------: | ---: | -----: | -----: |
| Gemini 3.8 Flash* | 92.9 | 91.3 | 95.2 | 92.2 |
| Datalab accurate | 92.7 | 90.8 | 91.8 | 95.6 |
| Datalab balanced | 91.6 | 90.0 | 89.2 | 95.5 |
| Reducto | 90.8 | 85.4 | 91.2 | 95.8 |
| LlamaParse | 90.4 | 88.2 | 92.6 | 90.4 |
_\* Used in creating and verifying at least some tests. Full results, and a tool to score any slice of the benchmark, are in the [OmniParseBench post](/blog/omni-parse-bench)._
**olmOCR-bench.** Chandra 2.5 scores **87.4** on olmOCR-bench, up from 86.2 for Chandra OCR 2, our open-source model. Both use LightOn's PP3, the benchmark postprocessing used in recent LightOnOCR and Infinity Parser results (it includes math rules from Infinity Parser's evaluation code). We don't think benchmark-specific postprocessing is good practice, so here are the scores raw, with each model's own postprocessing, and with PP3:
| Model | Raw | Own postprocessing | With PP3 |
| --------------- | ---: | -----------------: | -------: |
| Chandra 2.5 | 85.4 | **86.9** | **87.4** |
| Chandra OCR 2 | 85.1 | 85.8 | 86.2 |
| LightOnOCR-3-4B | 85.0 | 85.4 | 86.0 |
_Our runs: olmocr 0.4.27, olmOCR-bench revision 54a96a6. Headers and footers are left out. LightOnOCR's own postprocessing is LightOn's escaped-dollar fix, and its PP3 column includes it, as in LightOn's own results. LightOnOCR-3-4B numbers are our reproduction of LightOn's pipeline. LightOn reports 86.3._
## Faster in every mode
Chandra 2.5 is faster in every mode. Here is what API users waited for, end to end (upload, queueing, the full pipeline and getting the result back), for every successful single-page request to the `convert` and `marker` endpoints:
| Mode | p50 before | p50 after | Change | p90 before | p90 after | Change |
| -------- | ---------: | --------: | -----: | ---------: | --------: | -----: |
| fast | 12.2 s | 7.0 s | -43% | 31.6 s | 17.0 s | -46% |
| balanced | 12.9 s | 7.5 s | -42% | 30.3 s | 14.7 s | -51% |
| accurate | 18.4 s | 11.1 s | -40% | 46.7 s | 30.9 s | -34% |
_Single-page `/convert` and `/marker` requests, end to end, one week before and after the release._
Median latency is 40-43% lower in every mode, and p90 latency is 34-51% lower.
## Try it
Chandra 2.5 is live in the [API](/auth/sign_up) and the [playground](/playground). For on-premises deployments, contact us at [support@datalab.to](mailto:support@datalab.to).
If you have hard documents you want us to try, send them to [support@datalab.to](mailto:support@datalab.to), or find me on [Twitter](https://twitter.com/VikParuchuri).